This is the second post in the Parsing SMILES series:
- From SMILES Strings To Molecular Graphs
- Lexical Analysis (this post)
Introduction
In this post we write the lexer, which breaks a SMILES string into tokens. Tokens are the smallest chunks of characters that carry meaning in a given context.
The lexer is the first of the three stages we met in the first post:
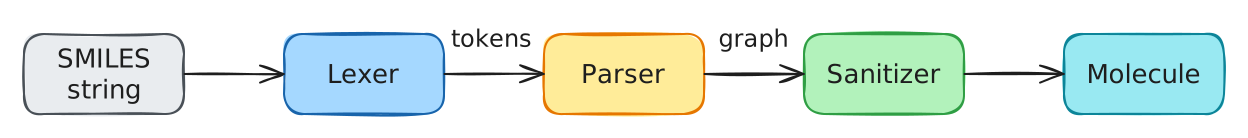
The lexer reads the SMILES string one character at a time and passes a list of tokens to the parser, which we will write in the next post. The lexer does not check how the tokens are arranged: it accepts C(C without complaint, because every character in it forms a valid token. It leaves the unclosed branch for the parser to report.
The code for this series lives in the smiles-parsing repository on GitHub. You can write it from scratch as you read, or clone the repository and check out the finished code for this post with git checkout part-2-lexer.
Most of a SMILES lexer is a simple loop over the characters. Two things make it more than that. First, some tokens are more than one character long, such as Cl, %12 and @@. Second, some characters change meaning with context: - is a single bond in C-C but a negative charge in [O-].
Setting up the project
We use uv to manage the Python project. uv is a Python package and project manager: it creates the virtual environment, installs dependencies and runs commands inside that environment. For this series we will use Python 3.10 or later, since we use the match statement, which arrived in Python 3.10.
Create the project as a library, so the code lives in an importable package:
uv init --lib --python ">=3.10" smiles-parsing
cd smiles-parsing
uv add --dev pytest ruff
--python ">=3.10" sets the oldest Python the project supports. uv then uses an installed Python 3.10 or later, or downloads one if none is installed. If git is installed, uv init also initializes the project folder as a git repository. It also creates a src/smiles_parsing/__init__.py with a hello() function, which we don’t need, so empty that file.
We also add two development dependencies: pytest to run tests and ruff to lint and format the code. By the end of this post, the files we work on will look like this (uv also creates a few files we don’t edit, such as uv.lock and py.typed):
smiles-parsing/
├── pyproject.toml
├── src/
│   └── smiles_parsing/
│       ├── __init__.py
│       ├── __main__.py
│       ├── lexer.py
│       └── tokens.py
└── tests/
    ├── test_main.py
    └── test_lexer.py
tokens.py defines what a token is, lexer.py contains the logic to turn a SMILES string into tokens, and __main__.py lets us run the lexer from the command line.
Choosing the tokens
The token types follow the OpenSMILES grammar. In CC(=O)O, for example, C and O are elements, = is a bond, and the parentheses mark a branch.
We split bracket atoms into their parts: [13CH4] becomes [, 13, C, H4, and ]. The parser checks their order.
We define the token types in an enum. auto() assigns each a unique value:
# src/smiles_parsing/tokens.py
from dataclasses import dataclass
from enum import Enum, auto


class TokenType(Enum):
    # Atoms
    ELEMENT = auto()  # C, Cl, and any element symbol inside brackets
    AROMATIC = auto()  # c, n, and se or as inside brackets
    WILDCARD = auto()  # *

    # Bonds and structure
    BOND = auto()  # - = # $ : / \
    DOT = auto()  # .
    BRANCH_START = auto()  # (
    BRANCH_END = auto()  # )
    RING_NUMBER = auto()  # 1 or %12

    # Bracket atoms, such as [13CH4] or [NH4+:1]
    BRACKET_START = auto()  # [
    BRACKET_END = auto()  # ]
    ISOTOPE = auto()  # 13
    CHIRALITY = auto()  # @, @@, @TH1, @OH12
    HYDROGEN_COUNT = auto()  # H or H4
    CHARGE = auto()  # +, -, +2, -12, ++ or --
    ATOM_CLASS = auto()  # :1
The token class
A token holds three things:
type: one of theTokenTypevalues.lexeme: the text the token was made from, such as"Cl"or"13".span: where the lexeme sits in the input, as a pair of offsets(start, end).
# src/smiles_parsing/tokens.py, below TokenType
@dataclass(frozen=True, slots=True)
class Token:
    type: TokenType
    lexeme: str
    span: tuple[int, int]  # half-open, so source[start:end] == lexeme
The span is what lets errors point at the exact character that caused them, both in this post and in the parser and sanitizer later on. In CCl, the Cl token has the span (1, 3), since "CCl"[1:3] is "Cl".
frozen=True makes tokens read-only once created, so no later stage can change one by accident. slots=True stores the fields in fixed slots instead of a per-instance dictionary, which makes each token a little smaller.
A first lexer
The lexer walks through the input one character at a time, looks at the current character and decides which token starts there. It keeps two pieces of state: pos, the index of the current character, and tokens, the list of tokens found so far.
# src/smiles_parsing/lexer.py
from smiles_parsing.tokens import Token, TokenType


class Lexer:
    def __init__(self, source: str):
        self.source = source
        self.pos = 0
        self.tokens: list[Token] = []

    def lex(self) -> list[Token]:
        while self.pos < len(self.source):
            self._lex_token()
        return self.tokens
_lex_token() adds one token and moves pos past it.
Two small helpers do most of the bookkeeping. _peek() returns the character at pos, or a few places ahead of it, without moving pos, and _add() creates a token of a given length at pos and moves pos past it:
# src/smiles_parsing/lexer.py, in the Lexer class
    def _peek(self, offset: int = 0) -> str:
        """Return the character offset places ahead, or a NUL character past the end."""
        index = self.pos + offset
        return self.source[index] if index < len(self.source) else "\0"

    def _add(self, token_type: TokenType, length: int) -> None:
        end = self.pos + length
        self.tokens.append(
            Token(token_type, self.source[self.pos : end], (self.pos, end))
        )
        self.pos = end
Past the end of the input, _peek() returns the NUL character "\0", which we use as a sentinel to denote the end of the input.
Now the lexer itself. The core logic of _lex_token will be a Python match statement. It compares a value against a list of patterns, called cases, and runs the first one that matches. A case can be a literal, such as case "(":, or the wildcard _, which matches anything. A case can also have a guard, an if condition that must be true for the case to match.
In snippets that show class Lexer: ..., the constants go at the top of lexer.py, below the import, and the methods go inside the class. New classes, such as LexicalError below, go above Lexer, and the lex() function goes at the end of the file:
# src/smiles_parsing/lexer.py
DIGITS = "0123456789"
BONDS = "-=#$:/\\"


class Lexer:
    ...

    def _lex_token(self) -> None:
        char = self._peek()
        match char:
            case "(":
                self._add(TokenType.BRANCH_START, 1)
            case ")":
                self._add(TokenType.BRANCH_END, 1)
            case ".":
                self._add(TokenType.DOT, 1)
            case "*":
                self._add(TokenType.WILDCARD, 1)
            case _ if char in BONDS:
                self._add(TokenType.BOND, 1)
            case _ if char in DIGITS:
                self._add(TokenType.RING_NUMBER, 1)
            case _ if char.isascii() and char.isalpha():
                self._lex_atom(ORGANIC_SUBSET)
            case _:
                raise self._error(f"unexpected character {char!r}", 1)
Letters go to _lex_atom(). We check isascii() first because isalpha() also accepts non-ASCII letters such as é, which can never be part of a valid SMILES token. SMILES only uses ASCII characters. _lex_atom() checks the letter against the organic subset (OpenSMILES section 3.1.5): the atoms the grammar allows outside brackets. This first version reads a single letter; we extend it later in this post:
# src/smiles_parsing/lexer.py
ORGANIC_SUBSET = {
    "B", "C", "N", "O", "P", "S", "F", "Cl", "Br", "I",
    "b", "c", "n", "o", "p", "s",
}  # fmt: skip


class Lexer:
    ...

    def _lex_atom(self, symbols: set[str]) -> None:
        symbol = self._peek()
        if symbol not in symbols:
            raise self._error(f"unknown atom symbol {symbol!r}", 1)
        token_type = TokenType.AROMATIC if symbol.islower() else TokenType.ELEMENT
        self._add(token_type, 1)
Lowercase symbols are aromatic atoms: atoms in an aromatic ring, such as the six c atoms of benzene, c1ccccc1. Uppercase symbols are ordinary elements. The # fmt: skip comment stops ruff’s formatter from putting each symbol on its own line.
Anything that does not form a token raises an error. For now, an error is an exception that remembers the message, the input and the span of the problem; we give it a readable display later in this post:
# src/smiles_parsing/lexer.py
class LexicalError(Exception):
    def __init__(self, message: str, source: str, span: tuple[int, int]):
        super().__init__(message)
        self.message = message
        self.source = source
        self.span = span


class Lexer:
    ...

    def _error(
        self, message: str, length: int, start: int | None = None
    ) -> LexicalError:
        if start is None:
            start = self.pos
        return LexicalError(message, self.source, (start, start + length))
_error() returns the exception instead of raising it, and each caller writes raise self._error(...). The span starts at pos unless the caller passes an earlier start, which the bracket atom code later in this post needs.
Finally, a small function hides the class from callers:
# src/smiles_parsing/lexer.py
def lex(source: str) -> list[Token]:
    return Lexer(source).lex()
This first version already handles a fair amount of SMILES. To try it, start Python inside the project with uv run python:
>>> from smiles_parsing.lexer import lex
>>> [token.lexeme for token in lex("CC(=O)O")]
['C', 'C', '(', '=', 'O', ')', 'O']
Maximum munch
Our first version of _lex_atom has the problem from the introduction. Given ClCCl, _lex_atom() reads C, and the next call fails on l, which is not an atom symbol:
>>> lex("ClCCl")
Traceback (most recent call last):
  ...
smiles_parsing.lexer.LexicalError: unknown atom symbol 'l'
The error’s span is (1, 2), the l. Br fails the same way.
The fix is called maximum munch: when several tokens could start at the current position, take the longest one. For atoms, that means trying the two-letter symbol before the one-letter symbol:
# src/smiles_parsing/lexer.py, replacing the first _lex_atom()
    def _lex_atom(self, symbols: set[str]) -> None:
        # Maximum munch: try the two-letter symbol first, so Cl is not C then l
        two_letters = self._peek() + self._peek(1)
        if two_letters in symbols:
            symbol = two_letters
        elif self._peek() in symbols:
            symbol = self._peek()
        else:
            raise self._error(f"unknown atom symbol {self._peek()!r}", 1)
        token_type = TokenType.AROMATIC if symbol.islower() else TokenType.ELEMENT
        self._add(token_type, len(symbol))
At the end of the input, _peek(1) returns the sentinel, so two_letters is something like "C\0", which is never a symbol, and the one-letter check takes over.
Maximum munch only considers the symbols allowed in the current context. Outside brackets, those are the organic subset, so Cs is a carbon followed by an aromatic sulfur, not cesium. Sc and Co work the same way: S then c, C then o. Cesium, scandium and cobalt can only be written inside brackets, as [Cs], [Sc] and [Co]. This is why _lex_atom() takes the set of symbols as a parameter: the bracket atom code later in this post passes a bigger set.
Ring numbers need maximum munch too. A digit on its own is a ring number from 0 to 9, and % followed by exactly two digits, such as %12, is a ring number from 0 to 99. We add a case for % to _lex_token():
# src/smiles_parsing/lexer.py, in Lexer._lex_token(), after case "*"
            case "%":
                self._lex_percent_ring_number()
# src/smiles_parsing/lexer.py, in the Lexer class
def _lex_percent_ring_number(self) -> None:
digits = self._count_digits(1)
if digits < 2:
raise self._error("'%' must be followed by two digits", 1 + digits)
self._add(TokenType.RING_NUMBER, 3)
def _count_digits(self, offset: int) -> int:
count = 0
while self._peek(offset + count) in DIGITS:
count += 1
return count_count_digits() counts the digits that start offset places ahead of pos. A % ring number always takes exactly two digits, so C%123 gives the ring numbers %12 and 3, which OpenSMILES section 3.4 says is the same as C3%12. With fewer than two digits, as in C%1, the lexer raises an error.
Bracket atoms
The meaning of a character can depend on its context. As we saw in the introduction, a - is a bond outside brackets and a charge inside them, so the lexer needs to know whether it is inside a bracket atom before it can decide which token the - starts. A lexer that uses context this way does context-sensitive lexing. In SMILES, the context is whether we are inside brackets:
| Character | Outside brackets | Inside brackets |
|---|---|---|
| Digits | Ring bonds: C12 is 1 and 2 | An isotope, as in [13C], or part of a count |
- | Single bond: C-C | Negative charge: [O-] |
: | Aromatic bond | Atom class: [CH3:1], a label number |
H | Not allowed | Hydrogen atom [H], or hydrogen count [CH4] |
| Letters | Organic subset only | Any element or aromatic symbol, including se and as |
Each set of rules is called a mode, and lexers that switch between sets of rules are said to have lexer modes. When _lex_token() sees [, it hands over to a second method that reads up to the closing ]. Two more cases go into _lex_token():
# src/smiles_parsing/lexer.py, in Lexer._lex_token(), after case "%"
            case "[":
                self._lex_bracket_atom()
            case "]":
                # _lex_bracket_atom() reads every ']' that closes a bracket atom
                raise self._error("']' without a matching '['", 1)
And here is the bracket mode. Its cases follow the order of the grammar’s rule for a bracket atom, which we saw in the first post:
bracket_atom ::= '[' isotope? symbol chiral? hcount? charge? class? ']'# src/smiles_parsing/lexer.py, in the Lexer class
def _lex_bracket_atom(self) -> None:
start = self.pos
self._add(TokenType.BRACKET_START, 1)
# Cases follow the grammar's order. Before the symbol, digits are an isotope
# and letters start the symbol; after it, H is a hydrogen count
seen_symbol = False
while self.pos < len(self.source):
char = self._peek()
match char:
case _ if char in DIGITS and not seen_symbol:
self._add(TokenType.ISOTOPE, self._count_digits(0))
case "*" if not seen_symbol:
self._add(TokenType.WILDCARD, 1)
seen_symbol = True
case _ if char.isascii() and char.isalpha() and not seen_symbol:
self._lex_atom(BRACKET_SYMBOLS)
seen_symbol = True
case "@":
self._lex_chirality()
case "H":
self._lex_hydrogen_count()
case "+" | "-":
self._lex_charge()
case ":":
self._lex_atom_class()
case "]":
self._add(TokenType.BRACKET_END, 1)
return
case _:
raise self._error(
f"unexpected character {char!r} in bracket atom", 1
)
raise self._error("bracket atom is not closed", self.pos - start, start=start)It has the same shape as _lex_token(), with different cases, plus one piece of state: the flag seen_symbol. The meaning of some characters depends on whether the atom symbol has been read yet. Before the symbol, digits form an isotope (OpenSMILES section 3.1.4), so [13C] gives the isotope 13. After it, an H starts a hydrogen count, so [CH4] gives the element C and the hydrogen count H4, while [2H] gives the isotope 2 and the element H. A digit or a second symbol after the symbol, as in [C1] or [CC], has no meaning and is an error. If the input ends before the ], the error spans the whole unclosed bracket atom, from the [ to the end. The helpers and symbols it uses come next.
The flag is all the lexer needs to read each part correctly. It does not check that the parts come in the order the grammar requires: [C+H], with the charge before the hydrogen count, lexes into [, C, +, H and ]. Checking the order is the parser’s job, as the next post shows.
The hydrogen count, charge and atom class each have a small method. The grammar allows at most one digit after H (section 3.1.2), up to two after a charge sign (section 3.1.3) and any number after : (section 3.1.7):
# src/smiles_parsing/lexer.py, in the Lexer class
    def _lex_hydrogen_count(self) -> None:
        digits = self._count_digits(1)
        if digits > 1:
            raise self._error("'H' can be followed by at most one digit", 1 + digits)
        self._add(TokenType.HYDROGEN_COUNT, 1 + digits)  # H or H4

    def _lex_charge(self) -> None:
        sign = self._peek()
        if self._peek(1) == sign:
            length = 2  # ++ or --
        else:
            length = 1 + min(self._count_digits(1), 2)  # +, -2
        if self._peek(length) in ("+", "-"):
            raise self._error("a charge cannot be followed by another sign", length + 1)
        self._add(TokenType.CHARGE, length)

    def _lex_atom_class(self) -> None:
        digits = self._count_digits(1)
        if digits == 0:
            raise self._error("':' must be followed by digits", 1)
        self._add(TokenType.ATOM_CLASS, 1 + digits)  # :1
So [NH4+:1], an ammonium ion with the atom class 1, gives [, N, H4, +, :1 and ]. A charge can have at most two signs, so nothing in the grammar matches [Fe+-] or [Fe+++], and _lex_charge() rejects them.
Letters go to the same _lex_atom() as before, with a bigger set of symbols: all 118 elements, plus the aromatic symbols allowed in brackets.
# src/smiles_parsing/lexer.py
ELEMENTS = {
    "H", "He", "Li", "Be", "B", "C", "N", "O", "F", "Ne",
    "Na", "Mg", "Al", "Si", "P", "S", "Cl", "Ar", "K", "Ca",
    "Sc", "Ti", "V", "Cr", "Mn", "Fe", "Co", "Ni", "Cu", "Zn",
    "Ga", "Ge", "As", "Se", "Br", "Kr", "Rb", "Sr", "Y", "Zr",
    "Nb", "Mo", "Tc", "Ru", "Rh", "Pd", "Ag", "Cd", "In", "Sn",
    "Sb", "Te", "I", "Xe", "Cs", "Ba", "La", "Ce", "Pr", "Nd",
    "Pm", "Sm", "Eu", "Gd", "Tb", "Dy", "Ho", "Er", "Tm", "Yb",
    "Lu", "Hf", "Ta", "W", "Re", "Os", "Ir", "Pt", "Au", "Hg",
    "Tl", "Pb", "Bi", "Po", "At", "Rn", "Fr", "Ra", "Ac", "Th",
    "Pa", "U", "Np", "Pu", "Am", "Cm", "Bk", "Cf", "Es", "Fm",
    "Md", "No", "Lr", "Rf", "Db", "Sg", "Bh", "Hs", "Mt", "Ds",
    "Rg", "Cn", "Nh", "Fl", "Mc", "Lv", "Ts", "Og",
}  # fmt: skip
BRACKET_SYMBOLS = ELEMENTS | {"b", "c", "n", "o", "p", "s", "se", "as"}
Maximum munch now does real work: [Sc] is scandium, [se] is aromatic selenium, and [nH] is an aromatic nitrogen followed by a hydrogen count, since nH is not a symbol.
Outside brackets, se and as are not allowed. c1ccsec1 would lex s and then fail on the e, which hides the real mistake, so _lex_atom() gets one more check, between the two-letter and the one-letter symbol:
# src/smiles_parsing/lexer.py, replacing the earlier _lex_atom()
    def _lex_atom(self, symbols: set[str]) -> None:
        # Maximum munch: try the two-letter symbol first, so Cl is not C then l
        two_letters = self._peek() + self._peek(1)
        if two_letters in symbols:
            symbol = two_letters
        elif two_letters in ("se", "as"):
            raise self._error(f"{two_letters!r} is only allowed inside brackets", 2)
        elif self._peek() in symbols:
            symbol = self._peek()
        else:
            raise self._error(f"unknown atom symbol {self._peek()!r}", 1)
        token_type = TokenType.AROMATIC if symbol.islower() else TokenType.ELEMENT
        self._add(token_type, len(symbol))
The last part of a bracket atom left to lex is chirality, which describes how the atoms around a center are arranged in space (OpenSMILES section 3.8). The grammar allows these forms:
chiral ::= '@' | '@@' | '@TH' [1-2] | '@AL' [1-2] | '@SP' [1-3]
         | '@TB' DIGIT DIGIT? | '@OH' DIGIT DIGIT?
So [C@H] gives the token @, [C@@H] gives @@ and [Fe@OH12] gives @OH12. The two letters after @ are the chirality class, such as TH for tetrahedral. Each form is one token, found by maximum munch:
# src/smiles_parsing/lexer.py
# The grammar lists the digits allowed after @TH, @AL and @SP. @TB and @OH
# take one or two digits, and their ranges are checked in a later stage.
CHIRALITY_DIGITS = {"TH": "12", "AL": "12", "SP": "123"}


class Lexer:
    ...

    def _lex_chirality(self) -> None:
        if self._peek(1) == "@":
            self._add(TokenType.CHIRALITY, 2)  # @@
            return
        chirality_class = self._peek(1) + self._peek(2)
        if chirality_class in CHIRALITY_DIGITS:
            if self._peek(3) not in CHIRALITY_DIGITS[chirality_class]:
                allowed = " or ".join(CHIRALITY_DIGITS[chirality_class])
                raise self._error(
                    f"'@{chirality_class}' must be followed by {allowed}", 3
                )
            self._add(TokenType.CHIRALITY, 4)  # @TH1
        elif chirality_class in ("TB", "OH"):
            digits = min(self._count_digits(3), 2)
            if digits == 0:
                raise self._error(
                    f"'@{chirality_class}' must be followed by a digit", 3
                )
            self._add(TokenType.CHIRALITY, 3 + digits)  # @TB1 or @OH12
        else:
self._add(TokenType.CHIRALITY, 1) # @@TH, @AL and @SP take one digit from a short list, so the lexer checks it directly and rejects [C@TH3]. @TB and @OH take one or two digits of any value. The grammar accepts @TB99, but only @TB1 to @TB20 have a meaning, and as we saw in the first post, that check belongs to the sanitizer.
Errors
So far our errors carry a message and a span, but printing one shows only the message. To be useful, an error should show where the problem is. We add a __str__() method, which Python calls to turn the exception into text:
# src/smiles_parsing/lexer.py, in the LexicalError class
    def __str__(self) -> str:
        # Errors happen at or before the first line break, so show only the first line
        line = self.source.splitlines()[0]
        start, end = self.span
        carets = " " * start + "^" * max(end - start, 1)
        return f"{self.message}\n{line}\n{carets}"
It prints the message, then the input, then a caret (^) under each character of the span:
unknown atom symbol 'X'
CXC
 ^
bracket atom is not closed
C[CH4
^^^^The lexer stops at the first error. It rejects input that cannot form a token in the current mode, which covers:
- Characters that are never valid, such as
XinCXCor?inC?. - A
]with no[before it. - Symbols that are not allowed in the current mode, such as
Houtside brackets, which must be written[H], or the aromaticseinc1ccsec1. - Tokens that start correctly but are not finished, are too long or end in a digit the grammar does not allow, such as
%1,[C:], theH12in[CH12]or@TH3. - A charge followed by another sign, such as
[Fe+-]or[Fe+++]. - Characters in the wrong place inside brackets, such as the
1in[C1]or the secondCin[CC]. - A
[with no closing]. This one looks like a question of arrangement, but the lexer needs the]to know where bracket mode ends, so an unclosed bracket atom is its error.
Input made of valid tokens passes, even when the tokens make no sense together. C(C, C==C and an unclosed ring such as C1CC are errors for the parser, and so is [C+H].
Stopping at the terminator
As we saw in the first post, a SMILES string ends at its terminator (OpenSMILES section 3.9): the first space, tab, line feed or carriage return. Anything after it, such as a molecule name, is not part of the SMILES. The lexer stops at the first terminator and leaves the rest of the input alone; splitting a file into SMILES and names is the job of the code that reads the file:
# src/smiles_parsing/lexer.py, replacing the earlier Lexer.lex()
TERMINATORS = " \t\n\r"


class Lexer:
    ...

    def lex(self) -> list[Token]:
        # The SMILES ends at the first terminator; what follows is not lexed
        while self.pos < len(self.source) and self._peek() not in TERMINATORS:
            self._lex_token()
        return self.tokens
For CCO ethanol, we get the tokens C, C and O. An input that starts with whitespace is an empty SMILES: " CCO" gives no tokens at all.
Inside brackets, a space is just an unexpected character, so [C H4] points at the space:
unexpected character ' ' in bracket atom
[C H4]
  ^
Testing the lexer
We test the lexer with pytest. pytest finds functions whose names start with test_ in files whose names start with test_, runs them, and reports any assert that fails. Its parametrize decorator runs one test function once for each item in a list, which suits a lexer: most tests are an input and the tokens we expect from it.
# tests/test_lexer.py
import pytest

from smiles_parsing.lexer import LexicalError, lex


def lexemes(source: str) -> list[str]:
    return [token.lexeme for token in lex(source)]


# Inputs the lexer can tokenize. Some, like C(C, are not valid SMILES: later
# stages reject them.
TOKENIZABLE = [
    ("CCO", ["C", "C", "O"]),
    ("C12CC12", ["C", "1", "2", "C", "C", "1", "2"]),
    ("ClCCl", ["Cl", "C", "Cl"]),
    ("C%12CC%12", ["C", "%12", "C", "C", "%12"]),
    ("Cs", ["C", "s"]),
    ("[13CH4]", ["[", "13", "C", "H4", "]"]),
    ("[O-]C(=O)C", ["[", "O", "-", "]", "C", "(", "=", "O", ")", "C"]),
    ("[Sc]", ["[", "Sc", "]"]),
    ("C(C", ["C", "(", "C"]),
    # ... more cases ...
]


@pytest.mark.parametrize(("source", "expected"), TOKENIZABLE)
def test_lexemes(source, expected):
    assert lexemes(source) == expected
One test checks a property that should hold for every input in the table: joining the lexemes gives back the input. If a token ever skipped a character or read one twice, this test would fail:
# tests/test_lexer.py
@pytest.mark.parametrize("source", [source for source, _ in TOKENIZABLE])
def test_lexemes_rebuild_the_source(source):
    assert "".join(token.lexeme for token in lex(source)) == source
Errors get their own table, with the span we expect each one to point at:
# tests/test_lexer.py
@pytest.mark.parametrize(
    ("source", "span"),
    [
        ("CXC", (1, 2)),
        ("H", (0, 1)),
        ("C%1", (1, 3)),
        ("[C", (0, 2)),
        ("[C@TH3]", (2, 5)),
        ("[C H4]", (2, 3)),
        ("[CH12]", (2, 5)),
        # ... more cases ...
    ],
)
def test_errors(source, span):
    with pytest.raises(LexicalError) as error:
        lex(source)
    assert error.value.span == span
pytest.raises checks that the code inside the with block raises the given exception, and gives us the exception to inspect. The repository has more cases and a few more tests, such as one that checks every span against its lexeme. Run the tests with:
uv run pytestTrying it out
A package can be run as a program if it has a __main__.py file. Ours prints one token per line:
# src/smiles_parsing/__main__.py
import sys

from smiles_parsing.lexer import LexicalError, lex


def main(smiles: str) -> int:
    try:
        tokens = lex(smiles)
    except LexicalError as error:
        print(error, file=sys.stderr)
        return 1
    for token in tokens:
        print(f"{token.type.name:<14} {token.lexeme!r:<8} {token.span}")
    return 0


if __name__ == "__main__":
    if len(sys.argv) != 2:
        sys.exit("usage: python -m smiles_parsing SMILES")
    sys.exit(main(sys.argv[1]))
The test calls main() directly. pytest’s capsys fixture captures what the function prints, so the test can check it:
# tests/test_main.py
from smiles_parsing.__main__ import main


def test_prints_one_token_per_line(capsys):
    assert main("CO") == 0
    assert capsys.readouterr().out.splitlines() == [
        "ELEMENT        'C'      (0, 1)",
        "ELEMENT        'O'      (1, 2)",
    ]


def test_prints_errors_to_stderr(capsys):
    assert main("CXC") == 1
    assert capsys.readouterr().err == "unknown atom symbol 'X'\nCXC\n ^\n"
Here is [13CH4], methane with a carbon-13 atom:
$ uv run python -m smiles_parsing "[13CH4]"
BRACKET_START  '['      (0, 1)
ISOTOPE        '13'     (1, 3)
ELEMENT        'C'      (3, 4)
HYDROGEN_COUNT 'H4'     (4, 6)
BRACKET_END    ']'      (6, 7)
And acetate, with a charge, a branch and a double bond:
$ uv run python -m smiles_parsing "[O-]C(=O)C"
BRACKET_START  '['      (0, 1)
ELEMENT        'O'      (1, 2)
CHARGE         '-'      (2, 3)
BRACKET_END    ']'      (3, 4)
ELEMENT        'C'      (4, 5)
BRANCH_START   '('      (5, 6)
BOND           '='      (6, 7)
ELEMENT        'O'      (7, 8)
BRANCH_END     ')'      (8, 9)
ELEMENT        'C'      (9, 10)
Exercise: try the lexer on real molecules. PubChem’s PUG REST API returns the SMILES of a list of compound IDs as plain text, one per line, for example https://pubchem.ncbi.nlm.nih.gov/rest/pug/compound/cid/1,2,3/property/SMILES/TXT. Fetch the first 100 compounds, lex each SMILES and count the token types. PubChem generates its SMILES with software, so if one fails to lex, the bug is more likely in our lexer than in the SMILES.
Getting the code
The code at the end of this post is tagged part-2-lexer in the smiles-parsing repository. To get it, clone the repository and check out the tag:
git clone https://github.com/msomierick/smiles-parsing.git
cd smiles-parsing
git checkout part-2-lexer
If you wrote the code yourself, commit it and tag it the same way, so the next post can start from it. If you haven’t used git on your machine before, set your name and email first with git config --global user.name and git config --global user.email:
git add .
git commit -m "Add the SMILES lexer"
git tag -a part-2-lexer -m "End of part 2: the lexer"
A note on performance
Our lexer keeps every token in a list and compares characters one case at a time, which is clear but not fast. A production lexer would work on raw bytes and stream each token to the parser as soon as it is read. It would also more likely be written in a faster, compiled language such as Rust or C++, especially for SMILES files with millions of records.
What’s next
We now have a list of tokens, each with a type, its text and its position. In the next post we write the parser. It reads those tokens, checks them against the grammar and builds the molecular graph as it goes. It also uses the spans to point at syntax errors, the same way the lexer does.